Definition · AI security
AI safety via debate
AI safety via debate is a method to supervise AI systems on tasks a person cannot check. Two AI models argue in turns. A human judge selects the model that said the most correct, useful thing. Studies from 2024 also use weaker models as judges. The method assumes that a lie is harder to defend than to refute.
Last reviewed
Key points
- Irving, Christiano and Amodei of OpenAI proposed debate in May 2018, for tasks too complex for a person to judge.
- Two AI models give answers, then make short statements in turns. A judge selects the winner.
- The method assumes "it is harder to lie than to refute a lie". The authors say tests must show this for each task.
- In studies from 2023 and 2024, debate made judges more correct on text that only the debaters could see.
- One open problem has no solution at this time. A dishonest model can hide an error in a long argument where nobody can find it.
How a debate works
The 2018 paper by Irving, Christiano and Amodei gives a game of five steps:
- The two AI models get the same question.
- Each model gives an answer. The two answers can be the same.
- The models make short statements in turns, to a set limit.
- The judge reads the debate and selects a winner.
- The game is zero sum. Each model tries only to win.
The judge has one rule: “The winner is the agent who said the most useful true thing.” The models train by self play on this zero sum game.
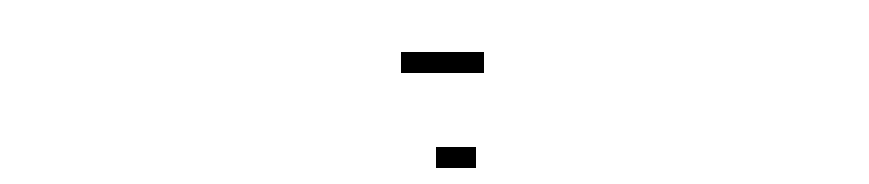
A model does not refute all of the other argument. The paper says that one error in one argument of the opponent is sufficient.
Why it matters
Training from human feedback, as in preference alignment, fails when a person cannot check the answer. Examples are a long proof, a large code change, or a research result.
Debate gives that hard work to a second model. The judge stays useful against a stronger system.
In practice
The UK AI Security Institute gave a security use case in May 2025. An AI agent that does research in an AI company could sabotage the work with incorrect results. The institute sketched how debate training could make such an agent honest.
The results below are from research setups. In each, the debaters know more than the judge.
| Study | Debaters and judge | Result |
|---|---|---|
| Irving et al., 2018 | Models show 6 MNIST pixels to a classifier | Judge correct 59.4%, then 88.9% |
| Michael et al., Nov 2023 | Humans debate, the judge does not read the story | 84% with debate, 74% with one consultant |
| Khan et al., 2024 (ICML) | LLMs debate, judges cannot see the text | 88% for human judges, 60% baseline |
| Kenton et al., Jul 2024 (Google DeepMind) | Strong LLMs debate, weaker LLMs judge | Debate beats consultancy on all tasks |
Two results limit these numbers:
- The difference was only data. Khan and colleagues say the difference between strong and weak “is only in access to information”. The judge was not less intelligent.
- Mixed results without hidden text. Kenton and colleagues found debate better than direct answers in one task type. There, the debaters saw text that the judge could not see. On other tasks “the results are mixed”.
Khan and colleagues also found that debaters trained to be more persuasive made judges more accurate. Kenton and colleagues saw the same effect, but “more modestly than in previous studies”.
Trade-offs
The 2018 paper and the work after it name these limits:
- Obfuscated arguments. Barnes and Christiano tested debate with human judges and debaters in 2020. A dishonest debater can make an argument with an error that is “very hard to locate”. They had no solution.
- Judge bias. Humans have belief bias. They judge an argument by what they believe, not by its logic.
- Cost. Debate needs human judges. The paper proposes models that predict the human verdict, to judge most debates.
- Theory is not practice. With perfect play, debate can answer all PSPACE questions, but a judge alone answers only NP questions. The authors call this “analogies only”.
- Not a full defence. The authors say debate “is not designed as a solution to robustness issues”. Other controls are necessary.
The AISI safety case sketch makes the open steps clear. It needs four claims to be true:
- the agent is good at the debate game
- good play in the game means the system is mostly honest
- the system does not become much less honest during deployment
- the deployment can tolerate some errors
The authors list open research problems that must be solved before this is “a compelling argument that an AI system is safe”.
Questions and answers
Is AI safety via debate used in AI products today?
The sources here show research, not a control in a product. The 2018 paper tested debate only on MNIST images. The 2023 and 2024 studies used questions about long texts. In May 2025 the UK AI Security Institute gave only a sketch of a safety case based on debate. It lists open research problems.
How is debate different from consultancy?
In consultancy, one expert argues for only one answer. That answer is correct half of the time. In debate, two experts argue for different answers. Michael and colleagues (2023) found judges correct 84% of the time with debate and 74% with consultancy. Kenton and colleagues (2024) found debate better than consultancy on all their tasks when the consultant got a random answer.
Sources
- AI safety via debatearXiv (Irving, Christiano, Amodei; OpenAI), 2 May 2018
- Debate update: Obfuscated arguments problemAI Alignment Forum (Beth Barnes), 23 Dec 2020
- Debate Helps Supervise Unreliable ExpertsarXiv (Michael et al.), 15 Nov 2023
- Debating with More Persuasive LLMs Leads to More Truthful AnswersarXiv (Khan et al., ICML 2024), 9 Feb 2024
- On scalable oversight with weak LLMs judging strong LLMsarXiv (Kenton et al., Google DeepMind), 5 Jul 2024
- An alignment safety case sketch based on debateUK AI Security Institute (Buhl, Pfau, Hilton, Irving), 6 May 2025