Definition · AI security
Carlini Wagner (C&W) attack
The Carlini Wagner (C&W) attack is a white box evasion attack that finds an adversarial example by optimisation. The attack looks for the smallest change to an input that makes a neural network give a target label. Nicholas Carlini and David Wagner published it in 2016. Three versions measure the change in L0, L2 or L∞ distance.
Last reviewed
Key points
- The C&W attack treats an adversarial example as an optimisation problem. It finds the smallest change to an input that gives a target label.
- It has three versions. L0 counts changed pixels, L2 measures total distance, and L∞ measures the largest change to one pixel.
- In the 2016 paper, the attacks had 100% success on networks with defensive distillation. No earlier attack worked there.
- The attacker must have full access to the model. The attack is slower than FGSM, but no attack took longer than a few minutes.
- The authors proposed it as a baseline to test new defences. The Adversarial Robustness Toolbox includes it.
How the C&W attack works
The C&W attack turns “fool the model” into one optimisation problem. It minimises the change plus c times a score. The score is low only when the model gives the target label.
| Part | What it does |
|---|---|
| Distance | L0, L2 or L∞ |
| Score f | Uses the logits, the raw outputs before softmax |
| Constant c | Sets the balance of small change against success. Binary search finds it |
| Confidence κ | Asks for a margin above the next label |
| tanh trick | Keeps each pixel in range |
| Optimizer | Adam, from more than one random start point |
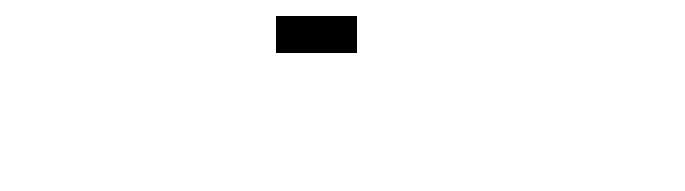
The L0 and L∞ versions start from the L2 attack. L0 fixes pixels with a small effect, in each iteration.
Why the C&W attack matters
The C&W attack showed that a defence can stop the attacks of its time and not be robust. Defensive distillation cut their success from 95% to 0.5%. On distilled networks, “all of the previous attacks fail”. The C&W attacks had 100% success in all three versions.
In practice
Results on the first 1,000 test images, undistilled models (Carlini and Wagner, 2016):
| Attack (MNIST) | Mean change | Success |
|---|---|---|
| C&W L2, random target | L2 1.76 | 100% |
| C&W L2, hardest target | L2 2.60 | 100% |
| FGSM, random target | L∞ 0.26 | 42% |
| FGSM, hardest target | none found | 0% |
Two uses of the C&W attack, and two related works by the same authors:
- To test a defence. The authors tell evaluators to “use a powerful attack (such as the ones proposed in this paper)” on the secured model.
- Against detectors (related work). In 2017, Carlini and Wagner showed that ten proposed detectors for adversarial examples “can be defeated by constructing new loss functions”.
- On audio (related work). In 2018, they used their own white box iterative optimisation attack on DeepSpeech from Mozilla. The new audio was “over 99.9% similar” and gave a phrase that they selected, with 100% success.
- In tools. The Adversarial Robustness Toolbox has CarliniL0Method, CarliniL2Method, CarliniLInfMethod and CarliniWagnerASR.
Trade-offs
- Full access. The attacker has the architecture and all the parameters of the network. For a model behind an API, the transfer test is closer. High confidence examples (κ = 40) from an ordinary model had 100% success on the distilled model.
- Speed. The L2 and L∞ attacks are “typically 10×−100× slower” than earlier attacks. No attack took longer than a few minutes for one image.
- Versions are not the same. The ART L2 attack uses line search, unlike the code of the authors. Report the library, the version and the parameters with a result.
- A strong attack is not proof. The authors give their attacks as a method to “construct an upper bound on the robustness”. Defensive distillation stopped the attacks of its time and then broke. An adaptive attack made for the defence is the stronger test.
Questions and answers
What is the difference between the C&W attack and FGSM?
FGSM takes one step along the sign of the gradient. The C&W attack runs a full optimisation with Adam, 10,000 iterations at each step. On MNIST with a random target, FGSM had 42% success. The C&W L2 attack had 100% success (Carlini and Wagner, 2016).
Does the C&W attack need access to the model?
Yes. The paper gives the attacker complete access to the network, with its architecture and all its parameters. A transfer test is also in the paper. High confidence examples from an ordinary model also fooled a model with defensive distillation.
Sources
- Towards Evaluating the Robustness of Neural NetworksarXiv (Carlini and Wagner), 16 Aug 2016
- Towards Evaluating the Robustness of Neural Networks (full text)arXiv (Carlini and Wagner), 22 Mar 2017
- Adversarial Examples Are Not Easily Detected: Bypassing Ten Detection MethodsarXiv (Carlini and Wagner), 20 May 2017
- Audio Adversarial Examples: Targeted Attacks on Speech-to-TextarXiv (Carlini and Wagner), 5 Jan 2018
- Adversarial Robustness Toolbox documentation, evasion attacksAdversarial Robustness Toolbox